WorkPublished Top storyAll news from that day
OpenAI reports building Pando, its Git backend, with Codex in 10 weeks
OpenAI says Pando cut median push latency by nearly 5x, and that agents used GPT-6 Astra to write Lean and TLA+ formalisations that found bugs. All figures are OpenAI's own.
Check our sources · 14 facts from 1 source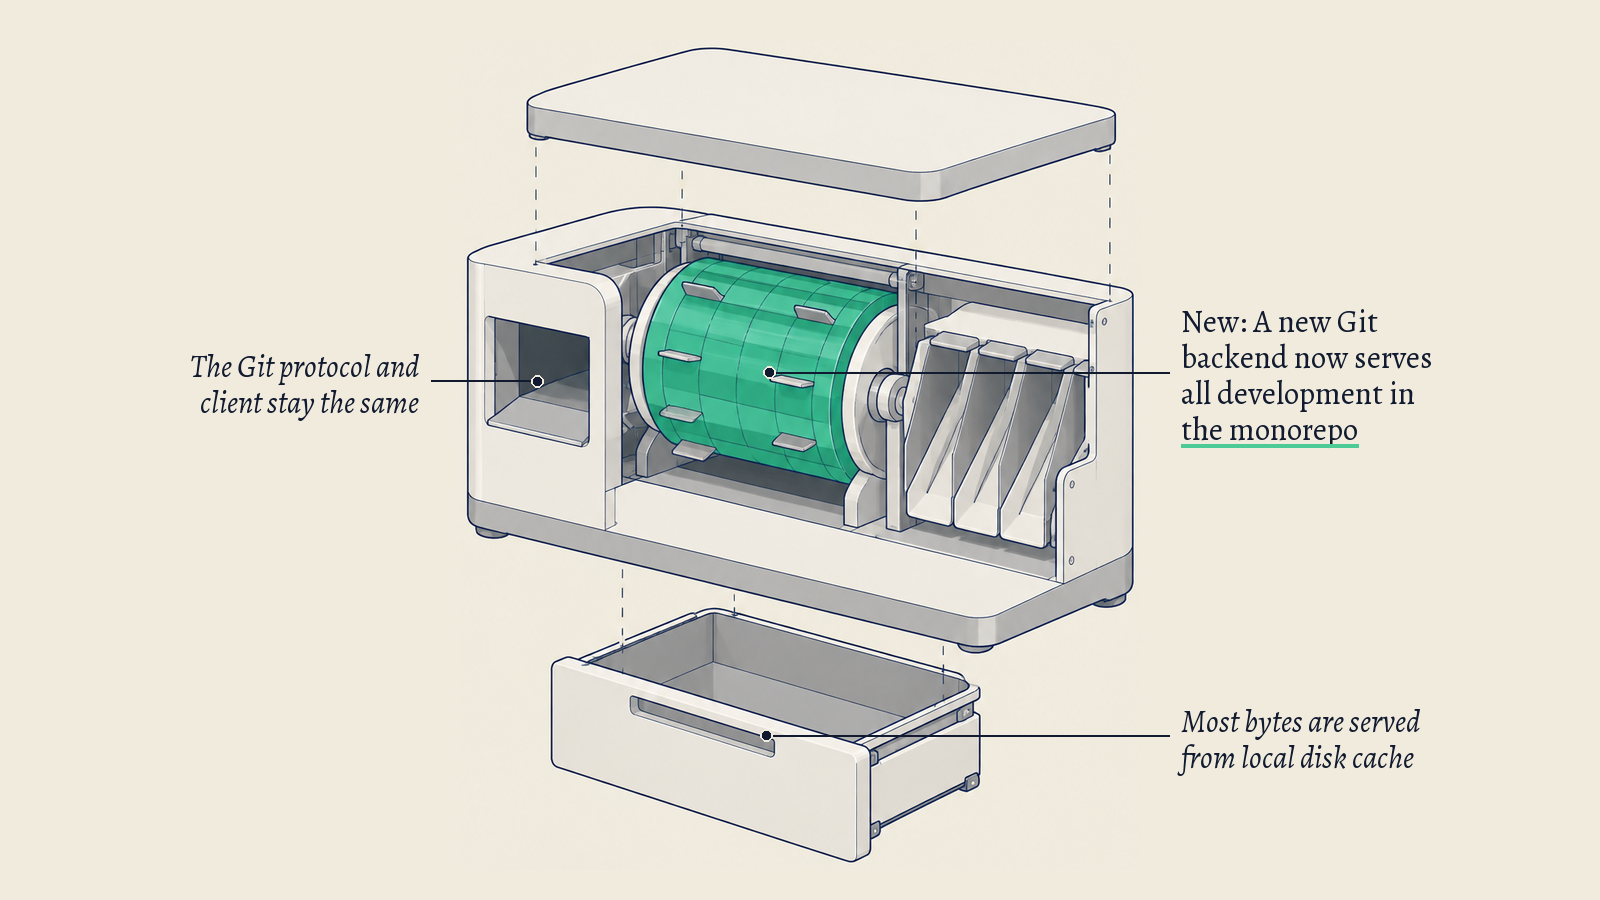 Illustration made with AI for ai notis
Key points
- OpenAI says Pando, its new Git backend, cut median push latency by nearly 5x in production and now delivers nearly a petabyte of Git data per day.
- OpenAI says its monorepo systems struggled from late last year, with reliability at times below 90%, and that Codex let engineers do far more work in parallel.
- OpenAI says one engineer designed the core, teams of agents implemented it and a handful of engineers deployed it, and that Pando began serving production traffic in April.
What happened
OpenAI replaced the backend serving its main code repository with a new system called Pando, and says it cut median push latency by nearly 5x and now delivers nearly a petabyte of Git data a day. The account is an engineering post of 2 November by OpenAI staff Aaron Friel, Taylor Blau and Ted Nyman, who are listed as Members of Technical Staff.
The authors say the old setup began to struggle around the end of last year as Codex let engineers run far more work in parallel, with slow fetches and pushes and failed merges, and reliability at times below 90%. Pando keeps the Git protocol and client, so engineers and agents did not change how they use Git, and it now powers all development in OpenAI's monorepo.
The post says Pando was built with Codex from kick-off to production in 10 weeks: one engineer designed the core, teams of agents implemented it and a handful of engineers deployed it, and it began serving production traffic in April. It names GPT-6 Astra as the model agents used to write Lean and TLA+ formalisations of the system to find and fix bugs.
Among the figures OpenAI gives for the deployment, Pando has served more than 57 terabytes of Git packs in a single hour, with more than 99% of those bytes from local disk cache, and cache hit rates on its pack delivery servers are over 99%. OpenAI says it is exploring ways to share the technology with its users.
Underlined sentences link to the facts we checked. Dotted words open a short explainer.
Fact 12 of 14 · from OpenAI, 2 Nov 2026
Pando has served more than 57 terabytes of Git packs in a single hour, with more than 99% of those bytes from local disk cache.
What it means for you
Our viewThis is one company's account of its own repository, so the figures show what OpenAI reports, not a result others can reproduce. Pando keeps the Git protocol and client, which means engineers did not have to change how they use Git.
OpenAI names GPT-6 Astra as the model agents used to write formal specifications of the system, and says that work was used to find and fix bugs. OpenAI says only that it is exploring ways to share the technology.
If you run a large Git monorepo, record your own push latency and failure rates now, so you have a baseline if the technology becomes available.
It adds no new facts.
Your reaction
We count reactions per story and day, never who reacted. The counts help us choose what goes in the monthly issue. If you are signed in, your own page shows yours too.
We count reactions per story and day, never who reacted. They help choose what goes in the monthly issue.
Check our sources
Every sentence above is checked against this source.
1 Scaling Git at OpenAI
Open the source archived copy-
OpenAI's engineering post "Scaling Git at OpenAI", dated 2 November 2026, is credited to Aaron Friel, Taylor Blau and Ted Nyman, Members of Technical Staff.
citeOpenAI November 2, 2026 ... Scaling Git at OpenAI ... By Aaron Friel, Taylor Blau, and Ted Nyman, Members of Technical Staff
-
OpenAI says it built Pando, a new backend for Git repositories, and that Pando now powers all development in OpenAI's monorepo.
citeWe built Pando, a new backend for Git repositories, without interrupting any engineering work or changing how our team uses Git. Pando now powers all development in OpenAI's monorepo.
-
OpenAI says that in production Pando cut median push latency by nearly 5x.
citeIn production, Pando cut median push latency by nearly 5x.
-
OpenAI says Pando now delivers nearly a petabyte of Git data per day.
citeIt now delivers nearly a petabyte of Git data per day.
-
OpenAI says that starting around the end of last year its systems supporting the monorepo struggled, with slow fetches and pushes and failed merges, and reliability at times falling below 90%.
citeStarting around the end of last year, the systems supporting our monorepo were struggling to keep up. We suffered slow fetches and pushes along with failed merges, with reliability at times falling below 90%.
-
OpenAI says Codex changed the scale and pace of development at OpenAI, enabling engineers to do far more work in parallel.
citeCodex has changed the scale and pace of development at OpenAI, enabling engineers to do far more work in parallel. That means more branches and pushes, more merges, and more fetches and clones from development environments, research jobs, and CI.
-
OpenAI says Pando retains compatibility with the Git protocol and client, so engineers and agents could adopt it without changing how the team uses Git.
citeWe met these goals while retaining compatibility with the Git protocol and client, enabling both our engineers and agents to seamlessly adopt Pando into their existing workflows.
-
OpenAI says it built Pando with Codex, moving from kick-off to production in just 10 weeks.
citeWe built Pando with Codex, moving from kick-off to production, in just 10 weeks.
-
OpenAI says the core of Pando was designed by a single engineer, implemented by teams of agents, and deployed by a handful of engineers.
citeThe core of Pando was designed by a single engineer, implemented by teams of agents, and deployed by a handful of engineers.
-
OpenAI says Pando began serving production traffic in April of this year.
citePando began serving production traffic in April of this year
-
OpenAI says that using GPT-6 Astra, agents wrote Lean and TLA+ to formalize a theory of Pando that was used to find and fix bugs in the implementation.
citeUsing GPT‑6 Astra, agents wrote Lean and TLA+ to formalize a “theory of Pando” that we used to find and fix bugs in the implementation, and prove properties of the system.
-
OpenAI says Pando has served more than 57 terabytes of Git packs in a single hour, with more than 99% of those bytes from local disk cache.
citePando has served more than 57 terabytes of Git packs in a single hour, with more than 99% of those bytes from local disk cache.
-
OpenAI says consistent hashing routes requests for a packfile to its Express pack delivery servers, with cache hit rates of over 99%.
citeWe use consistent hashing to route requests for a packfile to Express servers, with cache hit rates of over 99%.
-
OpenAI says it is currently exploring ways to share the technology that makes Pando possible with its users.
citeWe're currently exploring ways to share the technology that makes Pando possible with our users.
Every sentence above is checked against this source. Each fact has its own address you can cite.
Source 1 · OpenAI · 2 Nov 2026
Scaling Git at OpenAI
OpenAI's engineering post "Scaling Git at OpenAI", dated 2 November 2026, is credited to Aaron Friel, Taylor Blau and Ted Nyman, Members of Technical Staff.
OpenAI November 2, 2026 ... Scaling Git at OpenAI ... By Aaron Friel, Taylor Blau, and Ted Nyman, Members of Technical Staff
OpenAI says it built Pando, a new backend for Git repositories, and that Pando now powers all development in OpenAI's monorepo.
We built Pando, a new backend for Git repositories, without interrupting any engineering work or changing how our team uses Git. Pando now powers all development in OpenAI's monorepo.
OpenAI says that in production Pando cut median push latency by nearly 5x.
In production, Pando cut median push latency by nearly 5x.
Show all 14 factsShow fewer facts
OpenAI says Pando now delivers nearly a petabyte of Git data per day.
It now delivers nearly a petabyte of Git data per day.
OpenAI says that starting around the end of last year its systems supporting the monorepo struggled, with slow fetches and pushes and failed merges, and reliability at times falling below 90%.
Starting around the end of last year, the systems supporting our monorepo were struggling to keep up. We suffered slow fetches and pushes along with failed merges, with reliability at times falling below 90%.
OpenAI says Codex changed the scale and pace of development at OpenAI, enabling engineers to do far more work in parallel.
Codex has changed the scale and pace of development at OpenAI, enabling engineers to do far more work in parallel. That means more branches and pushes, more merges, and more fetches and clones from development environments, research jobs, and CI.
OpenAI says Pando retains compatibility with the Git protocol and client, so engineers and agents could adopt it without changing how the team uses Git.
We met these goals while retaining compatibility with the Git protocol and client, enabling both our engineers and agents to seamlessly adopt Pando into their existing workflows.
OpenAI says it built Pando with Codex, moving from kick-off to production in just 10 weeks.
We built Pando with Codex, moving from kick-off to production, in just 10 weeks.
OpenAI says the core of Pando was designed by a single engineer, implemented by teams of agents, and deployed by a handful of engineers.
The core of Pando was designed by a single engineer, implemented by teams of agents, and deployed by a handful of engineers.
OpenAI says Pando began serving production traffic in April of this year.
Pando began serving production traffic in April of this year
OpenAI says that using GPT-6 Astra, agents wrote Lean and TLA+ to formalize a theory of Pando that was used to find and fix bugs in the implementation.
Using GPT‑6 Astra, agents wrote Lean and TLA+ to formalize a “theory of Pando” that we used to find and fix bugs in the implementation, and prove properties of the system.
OpenAI says Pando has served more than 57 terabytes of Git packs in a single hour, with more than 99% of those bytes from local disk cache.
Pando has served more than 57 terabytes of Git packs in a single hour, with more than 99% of those bytes from local disk cache.
OpenAI says consistent hashing routes requests for a packfile to its Express pack delivery servers, with cache hit rates of over 99%.
We use consistent hashing to route requests for a packfile to Express servers, with cache hit rates of over 99%.
OpenAI says it is currently exploring ways to share the technology that makes Pando possible with its users.
We're currently exploring ways to share the technology that makes Pando possible with our users.
Topics
The morning email
On the mornings we publish: the three top stories and up to four short ones. Free.
We email you a link to confirm. An issue may include one sponsor, always labelled Sponsored · Advertisement. Our emails count opens and clicks, not who made them. Unsubscribe in one click. What we keep