ResearchPublished ExplainedAll news from that day
Ongoing case: Watermarks on AI-made content 5 stories
How text watermarks work and what EU Article 50 requires
A text watermark shifts how a model samples tokens using a secret key, and a detector tests for it; the EU marking duty in Article 50 applies from 2 August 2026.
Check our sources · 12 facts from 4 sources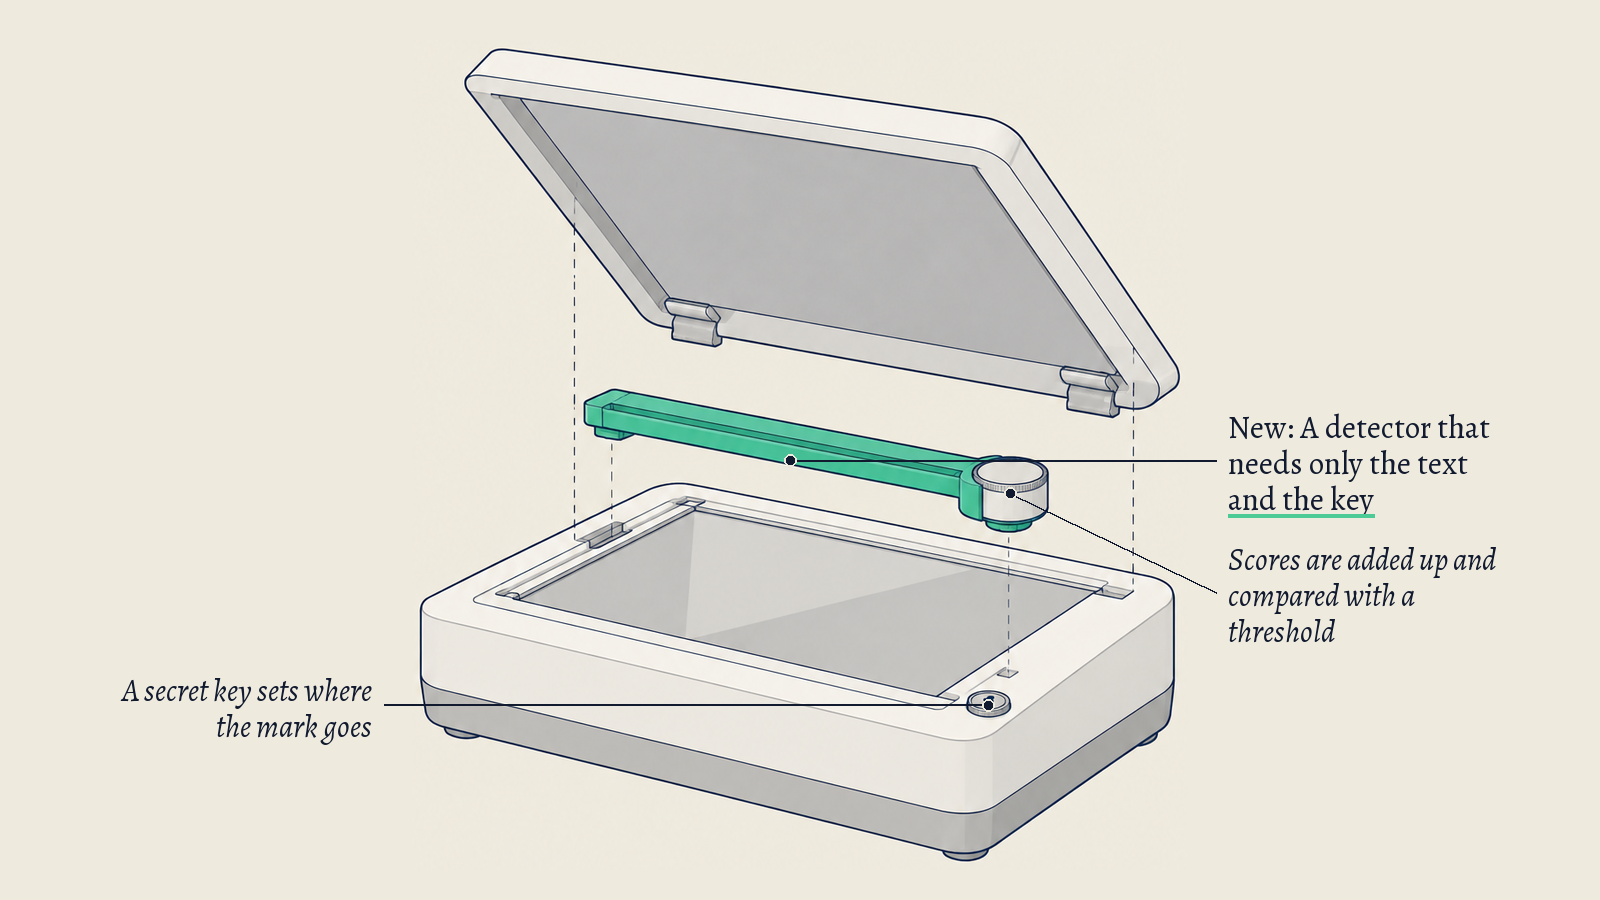 Illustration made with AI for ai notis
Key points
- A text watermark changes how a model samples each token, using pseudorandom values from a secret key and the preceding text; the detector needs only the text and the key.
- OpenAI's textGrain report says the detector adds up per-token scores and declares a watermark when the sum exceeds a threshold that sets the false positive rate under the report's assumptions.
- The European Commission says the Article 50 transparency obligations apply from 2 August 2026; Article 50(2) requires providers to mark outputs in a machine-readable, detectable format.
What happened
Article 50(2) of the EU AI Act requires providers of AI systems that generate synthetic audio, image, video or text to mark outputs in a machine-readable format so they are detectable as artificially generated.
The same article says the technical solutions must be effective, interoperable, robust and reliable as far as is technically feasible. The European Commission says these obligations apply from 2 August 2026, while its Code of Practice on marking AI-generated content is a voluntary way to show compliance.
A language model writes text one token at a time, sampling each token, which is a word or part of a word, from a prediction that depends on the preceding text. A text watermark changes that sampling using pseudorandom values derived from a secret key and the preceding text.
OpenAI's textGrain does this and limits how much sampling randomness it removes, using an entropy budget. To detect it, the detector needs only the text and the secret key. It rebuilds the keyed values at each position, scores each observed token, adds the scores up, and compares the sum with what unwatermarked text would give.
It declares a watermark when the sum is high enough that unwatermarked text would rarely reach it, which sets the false positive rate under the report's assumptions.
OpenAI says detection depends on length and content: at a 1% target false positive rate it found watermarks in about 80% of 200-token passages and about 95% of 400-token passages.
Editing weakens the signal, since replacing 10% of words with synonyms cut detection from about 92% to 66% on 400-token passages, and replacing 25% cut it to 17%. OpenAI also says a missing watermark does not prove human authorship, and a detected one does not identify the user.
Underlined sentences link to the facts we checked. Dotted words open a short explainer.
Fact 1 of 12 · from EUR-Lex, Official Journal of the European Union, 13 Jun 2024
2. Providers of AI systems, including general-purpose AI systems, generating synthetic audio, image, video or text content, shall ensure that the outputs of the AI system are marked in a machine-readable format and detectable as artificially generated or manipulated.
Fact 10 of 12 · from OpenAI, 5 Oct 2026
At a target false positive rate of 1%, our detector identified watermarks in about 80% of 200-token passages, compared with about 95% of 400-token passages, for content such as psychology. Detection rates were substantially lower for content such as mathematics, where there is less flexibility in word choice.
Fact 12 of 12 · from OpenAI, 5 Oct 2026
A watermark does not identify the user. ... The absence of a detected watermark does not prove human authorship.
What it means for you
Our viewDetection is a statistical test. It reports whether the summed score reaches a level unwatermarked text would rarely reach, so the threshold chosen sets how often it wrongly flags ordinary text.
OpenAI says detection depends on length and content, that editing weakens the signal, and that a missing watermark does not prove human authorship. Article 50 puts the marking duty on providers of AI systems.
If you publish AI-generated text in the EU, ask your model provider how its outputs are marked from 2 August 2026 and how you can check them, and keep a record of which texts came from a model.
It adds no new facts.
Your reaction
We count reactions per story and day, never who reacted. The counts help us choose what goes in the monthly issue. If you are signed in, your own page shows yours too.
We count reactions per story and day, never who reacted. They help choose what goes in the monthly issue.
Check our sources
Every sentence above is checked against these 4 sources.
1 Regulation (EU) 2024/1689 (AI Act), Article 50
Open the source archived copy-
Article 50(2) of the AI Act says providers of AI systems, including general-purpose AI systems, generating synthetic audio, image, video or text content shall ensure the outputs are marked in a machine-readable format and detectable as artificially generated or manipulated.
cite2. Providers of AI systems, including general-purpose AI systems, generating synthetic audio, image, video or text content, shall ensure that the outputs of the AI system are marked in a machine-readable format and detectable as artificially generated or manipulated.
-
Article 50(2) says providers shall ensure their technical solutions are effective, interoperable, robust and reliable as far as this is technically feasible, taking into account the specificities and limitations of various types of content, the costs of implementation and the generally acknowledged state of the art.
citeProviders shall ensure their technical solutions are effective, interoperable, robust and reliable as far as this is technically feasible, taking into account the specificities and limitations of various types of content, the costs of implementation and the generally acknowledged state of the art, as may be reflected in relevant technical standards.
2 Code of Practice on marking and labelling of AI-generated content
Open the source archived copy-
The European Commission says the Article 50 transparency obligations are applicable from 2 August 2026, and that adherence to its Code of Practice on transparency of AI-generated content is voluntary while the Article 50 requirements are legal obligations.
cite
3 textGrain: Entropy-Calibrated Watermarking for Language Model Text
Open the source archived copy-
OpenAI's textGrain technical report says a language model generates text one token at a time, sampling each token (a word or part of a word) from a next-token prediction distribution determined by the preceding text.
citeA language model generates text one token at a time, sampling each token (a word or part of a word) from a next token prediction (NTP) distribution determined by the preceding text.
-
The report says watermarking embeds a statistical signal by modifying this sampling using pseudorandom values derived from a secret key and the preceding context.
citeWatermarking embeds a statistical signal by modifying this sampling using pseudorandom values derived from a secret key and the preceding context
-
The report says textGrain applies an entropy budget that limits the average loss of sampling entropy to a fraction of the next-token prediction entropy.
citeAn entropy budget limits the average loss of sampling entropy to a fraction ... of the NTP entropy.
-
The report says the detector requires only the generated text and the secret key, and does not need to know the budget used during generation.
citeThe detector requires only the generated text and the secret key and does not need to know the budget used during generation.
-
The report says the detector reconstructs the keyed values at each scored position, derives a score from the observed token, and sums the scores to compare with the distribution of that sum for unwatermarked text.
citeThe context window and key reconstruct the cost table and selected column ... The cost for the observed block ... is transformed into the score ... Repeating this procedure at the scored positions yields Y1, ..., Yn. Their sum is compared with its distribution under unwatermarked text to test for a watermark.
-
The report says a watermark is declared when the sum exceeds the (1 - alpha) quantile of that distribution, so that under its stated assumptions the conditional false positive rate is alpha.
citewe declare a watermark when Sn exceeds this distribution's (1 - alpha) quantile. The conditional false positive rate is alpha under these assumptions
4 Our approach to EU text provenance rules
Open the source archived copy-
OpenAI says that at a target false positive rate of 1%, its detector identified watermarks in about 80% of 200-token passages, compared with about 95% of 400-token passages, for content such as psychology, and detection was substantially lower for content such as mathematics.
citeAt a target false positive rate of 1%, our detector identified watermarks in about 80% of 200-token passages, compared with about 95% of 400-token passages, for content such as psychology. Detection rates were substantially lower for content such as mathematics, where there is less flexibility in word choice.
-
OpenAI says that in an evaluation of 400-token passages, replacing 10% of words with synonyms reduced detection from about 92% to 66%, and replacing 25% of words reduced it to 17%.
citeIn an evaluation of 400-token passages, replacing 10% of words with synonyms reduced detection from about 92% to 66%. Replacing 25% of words reduced it to 17%.
-
OpenAI says the absence of a detected watermark does not prove human authorship, and that a watermark does not identify the user.
citeA watermark does not identify the user. ... The absence of a detected watermark does not prove human authorship.
Every sentence above is checked against these 4 sources. Each fact has its own address you can cite.
Source 1 · EUR-Lex, Official Journal of the European Union · 13 Jun 2024
Regulation (EU) 2024/1689 (AI Act), Article 50
Article 50(2) of the AI Act says providers of AI systems, including general-purpose AI systems, generating synthetic audio, image, video or text content shall ensure the outputs are marked in a machine-readable format and detectable as artificially generated or manipulated.
2. Providers of AI systems, including general-purpose AI systems, generating synthetic audio, image, video or text content, shall ensure that the outputs of the AI system are marked in a machine-readable format and detectable as artificially generated or manipulated.
Article 50(2) says providers shall ensure their technical solutions are effective, interoperable, robust and reliable as far as this is technically feasible, taking into account the specificities and limitations of various types of content, the costs of implementation and the generally acknowledged state of the art.
Providers shall ensure their technical solutions are effective, interoperable, robust and reliable as far as this is technically feasible, taking into account the specificities and limitations of various types of content, the costs of implementation and the generally acknowledged state of the art, as may be reflected in relevant technical standards.
Source 2 · European Commission
Code of Practice on marking and labelling of AI-generated content
The European Commission says the Article 50 transparency obligations are applicable from 2 August 2026, and that adherence to its Code of Practice on transparency of AI-generated content is voluntary while the Article 50 requirements are legal obligations.
Source 3 · OpenAI · 5 Oct 2026
textGrain: Entropy-Calibrated Watermarking for Language Model Text
OpenAI's textGrain technical report says a language model generates text one token at a time, sampling each token (a word or part of a word) from a next-token prediction distribution determined by the preceding text.
A language model generates text one token at a time, sampling each token (a word or part of a word) from a next token prediction (NTP) distribution determined by the preceding text.
The report says watermarking embeds a statistical signal by modifying this sampling using pseudorandom values derived from a secret key and the preceding context.
Watermarking embeds a statistical signal by modifying this sampling using pseudorandom values derived from a secret key and the preceding context
The report says textGrain applies an entropy budget that limits the average loss of sampling entropy to a fraction of the next-token prediction entropy.
An entropy budget limits the average loss of sampling entropy to a fraction ... of the NTP entropy.
Show all 6 factsShow fewer facts
The report says the detector requires only the generated text and the secret key, and does not need to know the budget used during generation.
The detector requires only the generated text and the secret key and does not need to know the budget used during generation.
The report says the detector reconstructs the keyed values at each scored position, derives a score from the observed token, and sums the scores to compare with the distribution of that sum for unwatermarked text.
The context window and key reconstruct the cost table and selected column ... The cost for the observed block ... is transformed into the score ... Repeating this procedure at the scored positions yields Y1, ..., Yn. Their sum is compared with its distribution under unwatermarked text to test for a watermark.
The report says a watermark is declared when the sum exceeds the (1 - alpha) quantile of that distribution, so that under its stated assumptions the conditional false positive rate is alpha.
we declare a watermark when Sn exceeds this distribution's (1 - alpha) quantile. The conditional false positive rate is alpha under these assumptions
Source 4 · OpenAI · 5 Oct 2026
Our approach to EU text provenance rules
OpenAI says that at a target false positive rate of 1%, its detector identified watermarks in about 80% of 200-token passages, compared with about 95% of 400-token passages, for content such as psychology, and detection was substantially lower for content such as mathematics.
At a target false positive rate of 1%, our detector identified watermarks in about 80% of 200-token passages, compared with about 95% of 400-token passages, for content such as psychology. Detection rates were substantially lower for content such as mathematics, where there is less flexibility in word choice.
OpenAI says that in an evaluation of 400-token passages, replacing 10% of words with synonyms reduced detection from about 92% to 66%, and replacing 25% of words reduced it to 17%.
In an evaluation of 400-token passages, replacing 10% of words with synonyms reduced detection from about 92% to 66%. Replacing 25% of words reduced it to 17%.
OpenAI says the absence of a detected watermark does not prove human authorship, and that a watermark does not identify the user.
A watermark does not identify the user. ... The absence of a detected watermark does not prove human authorship.
Topics
The morning email
On the mornings we publish: the three top stories and up to four short ones. Free.
We email you a link to confirm. An issue may include one sponsor, always labelled Sponsored · Advertisement. Our emails count opens and clicks, not who made them. Unsubscribe in one click. What we keep