2026-10-17 notis CATEGORY Join
Show Read as Find Sections Models and releasesAgents and appsResearchMoney and computeLaws and rulingsSafety and securityAI at work More ArchiveModelsAboutCorrectionsThe numbersRSS
My notis
TODAY'S NEWS
October 2026 3 STORIES
MTWTFSS
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31

Days with a dot have news. See the archive.

The whole week ›
09:45
0/3
WEATHER THEME CARD SPACING

Today's news

today

My page

Kept in this browser only.

SAVED FOLLOWING COLLECTIONS READING SINCE
Nothing saved yet. Tap the bookmark on a card to keep it here. read today
all cases

No case followed yet.

Price changes Stories where a published price went up or down.
Models being retired Models being withdrawn, and gaps before a replacement is ready.
The day's top stories. Sign up
Compute 17 OCT

Huang says Nvidia is probably running about 40% of cloud providers' capex

Bg2 PodNemotronNvidiacapex
Jensen Huang | Does AI Revenue Justify Capex, '27 AI Bottlenecks, Singularity, Open vs Closed & more: a video from Bg2 Pod on YouTubeVideo: Bg2 Pod on YouTube

On the Bg2 Pod, published 15 October 2026, Nvidia chief executive Jensen Huang gave his own figures for per-gigawatt supply, capex share and startups' open-model use.

SOURCENVIDIA Newsroom · 2 sources
CHECKED17 Oct, 04:26
Compute watch read
Jensen Huang | Does AI Revenue Justify Capex, '27 AI Bottlenecks, Singularity, Open vs Closed & more: a video from Bg2 Pod on YouTube Compute / 17 OCT

Huang says Nvidia is probably running about 40% of cloud providers' capex

  • Huang says what Nvidia offers into one gigawatt rose "to 20 somewhat billion per gigawatt to now 40 plus per gigawatt" (54:11).
  • Huang says Nvidia's share of the world's capex was "in single digits" about six years earlier (54:39) and that with cloud providers "we're probably running about 40%" (54:46).
  • Huang says of the startups that rent Nvidia compute that "80% of them use open models" (1:06:15).

Jensen Huang, Nvidia's founder and chief executive, was interviewed on the Bg2 Pod. The video was published on the programme's YouTube channel on 15 October 2026.

Asked about Nvidia's growth, Huang said that what Nvidia offers into one gigawatt of data-centre capacity has risen "to 20 somewhat billion per gigawatt to now 40 plus per gigawatt" (54:11). The figure is his own, given in conversation.

On Nvidia's share of spending he said "Our percentage of the world's capex was in single digits" about six years earlier (54:39), and that with the world's cloud providers "we're probably running about 40%" (54:46).

Answering a question on whether the labs can keep growing their revenue, Huang began "People misunderstand what's going on" (1:01:58) and said "Nvidia represents call it 80% of the revenue share of AI infrastructure in the world today" (1:02:03).

On open models he said of the startups that rent Nvidia compute that "80% of them use open models" (1:06:15), and that "many of them taking Neotron" (1:06:35), which is the automatic captions' rendering of Nemotron, Nvidia's model family.

What it means for you Our view

These are Huang's own figures, given in conversation, and for the per-gigawatt number the transcript carries no unit beyond "billion" for the earlier values. A supplier's estimate of its share of customers' spending shows how it frames its position, but it is not an audited number. His remark that startups renting Nvidia compute mostly use open models is likewise his description, not a survey. If you plan capacity or negotiate GPU pricing, ask your cloud provider how much of your quoted price reflects accelerator costs, and compare that with what Huang says.

TAGSBg2 PodNemotronNvidiacapex
toned down Models 17 OCT

Hassabis says not releasing Google's early LaMDA was probably wrong

GoogleIntelligence SquaredLaMDA
Demis Hassabis: How AI Solves Impossible Problems: a video from Intelligence Squared on YouTubeVideo: Intelligence Squared on YouTube

In a 14-minute Intelligence Squared video published 15 October 2026, DeepMind chief Demis Hassabis, in discussion with Sebastian Mallaby, discussed Google's early LaMDA product.

SOURCEGoogle DeepMind · 2 sources
CHECKED17 Oct, 04:26
Models watch read
Demis Hassabis: How AI Solves Impossible Problems: a video from Intelligence Squared on YouTube Models / 17 OCT

Hassabis says not releasing Google's early LaMDA was probably wrong

  • Hassabis says "the Google Brain side of it had a product, a very early one", which the captions spell Lambda and which is LaMDA (00:12).
  • Of not releasing it, Hassabis says "there'd been a conscious decision not to release that, and it was obviously in retrospect probably the wrong decision" (00:19).
  • Hassabis says "there needs to be some more cooperation and coordination at an international level ideally" (13:38).

Demis Hassabis, co-founder and chief executive of Google DeepMind, spoke in a discussion with Sebastian Mallaby that Intelligence Squared published as a 14-minute video on 15 October 2026. The video's description points to the full discussion on Intelligence Squared+.

Hassabis said the Google Brain side had a very early product, called LaMDA (00:12 to 00:17); the automatic captions spell it "Lambda". Of the decision not to release it he said "there'd been a conscious decision not to release that, and it was obviously in retrospect probably the wrong decision" (00:19). He said he was not involved in that decision (00:26).

On the balance of risks he spoke of a "gnawing feeling that there's something much more important, much bigger than the commercial race" (13:10), and said "there needs to be some more cooperation and coordination at an international level ideally" (13:38).

What it means for you Our view

This is Hassabis's account in a short video, and he says he was not involved in the decision about LaMDA, so he speaks about it as an observer. His "gnawing feeling" that something matters more than the commercial race, and his call for international cooperation, are his views, not announcements of any Google policy. If your organisation decides when an AI feature ships, the practical point is that a company's own leader can judge a held-back release as probably wrong in hindsight. Before your next release decision, write down what you are waiting for and who will review the choice later.

TAGSGoogleIntelligence SquaredLaMDA
Tooling 17 OCT

How spend and rate limits cap what an AI agent costs

AnthropicClaude CodeRate limitsSpend limits
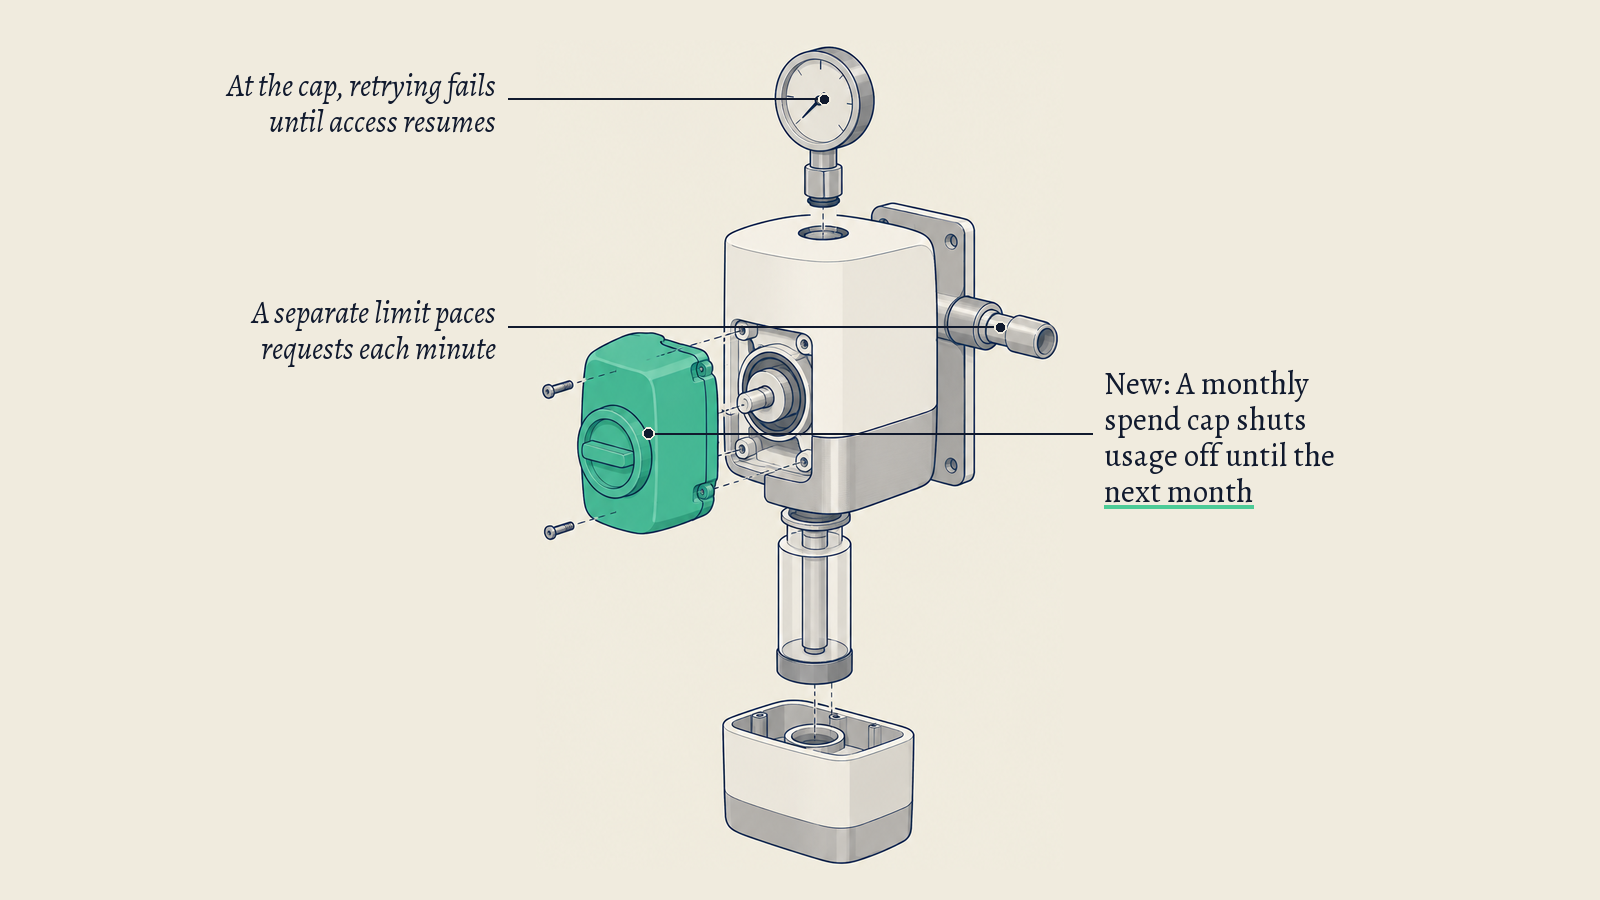
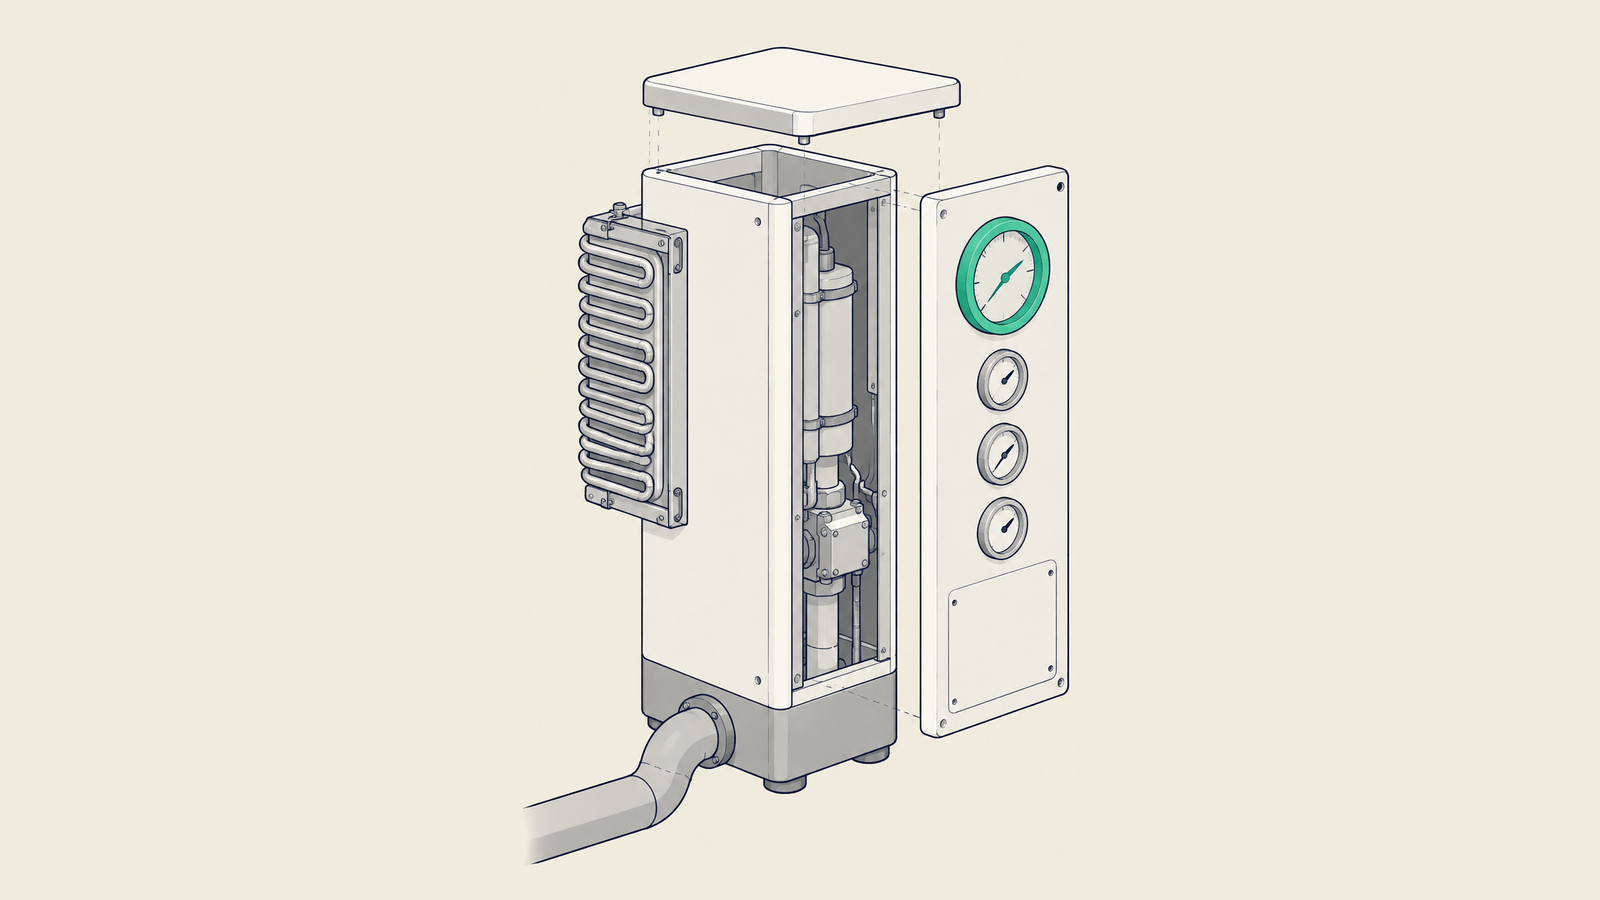
Illustration: A wall-mounted metering unit with a dial gauge and an outlet pipe; its green shut-off valve stands for the monthly spend cap that stops API usage.Illustration made with AI for ai notis

Anthropic's documentation separates monthly spend limits from per-minute rate limits and shows where each applies to API use and to Claude Code.

SOURCEAnthropic · 2 sources
CHECKED17 Oct, 04:26
Tooling read
Illustration: A wall-mounted metering unit with a dial gauge and an outlet pipe; its green shut-off valve stands for the monthly spend cap that stops API usage. Tooling / 17 OCT

How spend and rate limits cap what an AI agent costs

  • Anthropic's monthly spend cap is $500 on the Start tier, $1,000 on Build and $200,000 on Scale, with no cap on Custom.
  • At the cap, API usage pauses until 00:00 UTC on the first of the next month and requests return HTTP 429 without a retry-after header, so automatic retries fail.
  • Anthropic says Claude Code averages around $13 per developer per active day, and agent teams use approximately 7x more tokens than standard sessions in plan mode.

This page explains spend limits and rate limits using Anthropic's own documentation for its API and for Claude Code.

A spend limit and a rate limit are different things. Anthropic's rate-limit page says spend limits set a maximum monthly cost an organization can incur for API usage, while rate limits set the maximum number of API requests an organization can make over a defined period.

Each of the Start, Build and Scale tiers carries a monthly spend cap: $500, $1,000 and $200,000 respectively. Organizations on the Custom tier have no monthly spend cap, and their limits are arranged with their account team.

When the cap is reached, API usage pauses until 00:00 UTC on the first day of the next month, unless a higher limit is requested sooner. Requests then return HTTP 429, but without a retry-after header, so retrying, including the SDK's automatic retries, fails until access resumes. The error code to look for is enforced_spend_limit_reached.

An organization can also set its own spend limit below the tier cap, and the limit cannot exceed the tier's cap. When usage reaches a limit the organization set, requests return HTTP 400 with the error type invalid_request_error instead.

Rate limits work on a shorter clock. They are measured in requests per minute, input tokens per minute and output tokens per minute, and the API uses a token bucket algorithm, so capacity is continuously replenished up to a maximum. For most Claude models, cache-read input tokens do not count toward the input-token limit.

Limits can be set lower for each workspace, so one project cannot use up the whole organization's allowance. Workspace limits are set per limiter type, the default workspace cannot be limited, and the organization-wide limits always apply.

Anthropic's Claude Code cost page says Claude Code charges by API token consumption and that, across enterprise deployments, the average cost is around $13 per developer per active day and $150-250 per developer per month. Thinking tokens are billed as output tokens, subagents' requests still draw on usage, and a scheduled task fires on its interval even while the session is idle, sending the full context each time. The page says agent teams use approximately 7x more tokens than standard sessions when teammates run in plan mode.

Where the cap lives depends on how the model is reached. For Claude Console users it is workspace spend limits. For Claude for Teams and Enterprise it is a per-seat allowance that resets on a rolling five-hour window and a weekly window, with spend limits at organization, group or individual level for usage credits. On Amazon Bedrock, Google Cloud's Agent Platform and Microsoft Foundry, the page says spend controls live in the cloud provider's billing console.

What it means for you Our view

A spend limit caps the monthly bill and a rate limit paces requests, and an agent can run into either. The spend-cap response carries no retry-after header, so an agent that retries automatically keeps failing until access resumes. Anthropic's own figures also show how agents multiply token use: a scheduled task sends the full context each time it fires, even while the session is idle. If you run agents on the API, set a workspace spend limit below the tier cap, and make sure the agent stops instead of retrying, both on the HTTP 400 from your own limit and on the 429 with enforced_spend_limit_reached at the tier cap.

TAGSAnthropicClaude CodeRate limitsSpend limits
Anthropic · 2 sources tap to close
NOTHING IN THIS FILTER No story today matches. open the archive →
That's today's news: three stories.

The morning email

On the mornings we publish: the three top stories and up to four short ones. Free.

We email you a link to confirm. An issue may include one sponsor, always labelled Sponsored · Advertisement. Our emails count opens and clicks, not who made them. Unsubscribe in one click. What we keep

1 of 3
Jensen Huang | Does AI Revenue Justify Capex, '27 AI Bottlenecks, Singularity, Open vs Closed & more: a video from Bg2 Pod on YouTube Watch on YouTubeVideo: Bg2 Pod on YouTube

Compute · 17 OCT

Huang says Nvidia is probably running about 40% of cloud providers' capex

On the Bg2 Pod, published 15 October 2026, Nvidia chief executive Jensen Huang gave his own figures for per-gigawatt supply, capex share and startups' open-model use.

  • Huang says what Nvidia offers into one gigawatt rose "to 20 somewhat billion per gigawatt to now 40 plus per gigawatt" (54:11).
  • Huang says Nvidia's share of the world's capex was "in single digits" about six years earlier (54:39) and that with cloud providers "we're probably running about 40%" (54:46).
  • Huang says of the startups that rent Nvidia compute that "80% of them use open models" (1:06:15).
Checked 17 Oct, 04:26 · NVIDIA Newsroom · 2 sources
Demis Hassabis: How AI Solves Impossible Problems: a video from Intelligence Squared on YouTube Watch on YouTubeVideo: Intelligence Squared on YouTube

Models · 17 OCTnarrowed

Hassabis says not releasing Google's early LaMDA was probably wrong

In a 14-minute Intelligence Squared video published 15 October 2026, DeepMind chief Demis Hassabis, in discussion with Sebastian Mallaby, discussed Google's early LaMDA product.

  • Hassabis says "the Google Brain side of it had a product, a very early one", which the captions spell Lambda and which is LaMDA (00:12).
  • Of not releasing it, Hassabis says "there'd been a conscious decision not to release that, and it was obviously in retrospect probably the wrong decision" (00:19).
  • Hassabis says "there needs to be some more cooperation and coordination at an international level ideally" (13:38).
Checked 17 Oct, 04:26 · Google DeepMind · 2 sources
Illustration: A wall-mounted metering unit with a dial gauge and an outlet pipe; its green shut-off valve stands for the monthly spend cap that stops API usage. Illustration made with AI for ai notis

Tooling · 17 OCT

How spend and rate limits cap what an AI agent costs

Anthropic's documentation separates monthly spend limits from per-minute rate limits and shows where each applies to API use and to Claude Code.

  • Anthropic's monthly spend cap is $500 on the Start tier, $1,000 on Build and $200,000 on Scale, with no cap on Custom.
  • At the cap, API usage pauses until 00:00 UTC on the first of the next month and requests return HTTP 429 without a retry-after header, so automatic retries fail.
  • Anthropic says Claude Code averages around $13 per developer per active day, and agent teams use approximately 7x more tokens than standard sessions in plan mode.
Checked 17 Oct, 04:26 · Anthropic · 2 sources

You're all caught up

That's today's news: three stories.

You can join ai notis soon, to follow cases and keep stories on every device.

Follow us on Instagram and Threads

The morning email

On the mornings we publish: the three top stories and up to four short ones. Free.

We email you a link to confirm. An issue may include one sponsor, always labelled Sponsored · Advertisement. Our emails count opens and clicks, not who made them. Unsubscribe in one click. What we keep

No story today matches. Open the archive
Today's stories 3 STORIES

Today's stories

Sat 17 Oct · 3 STORIES
  1. Compute · 17 OCT

    Huang says Nvidia is probably running about 40% of cloud providers' capex

    Jensen Huang | Does AI Revenue Justify Capex, '27 AI Bottlenecks, Singularity, Open vs Closed & more: a video from Bg2 Pod on YouTubeVideo: Bg2 Pod on YouTube

    On the Bg2 Pod, published 15 October 2026, Nvidia chief executive Jensen Huang gave his own figures for per-gigawatt supply, capex share and startups' open-model use.

    Checked 17 Oct, 04:26 · NVIDIA Newsroom · 2 sourcesRead

  2. Models · 17 OCT · narrowed

    Hassabis says not releasing Google's early LaMDA was probably wrong

    Demis Hassabis: How AI Solves Impossible Problems: a video from Intelligence Squared on YouTubeVideo: Intelligence Squared on YouTube

    In a 14-minute Intelligence Squared video published 15 October 2026, DeepMind chief Demis Hassabis, in discussion with Sebastian Mallaby, discussed Google's early LaMDA product.

    Checked 17 Oct, 04:26 · Google DeepMind · 2 sourcesRead

  3. Tooling · 17 OCT

    How spend and rate limits cap what an AI agent costs

    Illustration: A wall-mounted metering unit with a dial gauge and an outlet pipe; its green shut-off valve stands for the monthly spend cap that stops API usage.Illustration made with AI for ai notis

    Anthropic's documentation separates monthly spend limits from per-minute rate limits and shows where each applies to API use and to Claude Code.

    Checked 17 Oct, 04:26 · Anthropic · 2 sourcesRead

Compute 17 OCT

Huang says Nvidia is probably running about 40% of cloud providers' capex

On the Bg2 Pod, published 15 October 2026, Nvidia chief executive Jensen Huang gave his own figures for per-gigawatt supply, capex share and startups' open-model use.

NVIDIA Newsroom · 2 sources·checked 17 Oct, 04:26
Bg2 PodNemotronNvidiacapex
Jensen Huang | Does AI Revenue Justify Capex, '27 AI Bottlenecks, Singularity, Open vs Closed & more: a video from Bg2 Pod on YouTubeVideo: Bg2 Pod on YouTube
toned down Models

Hassabis says not releasing Google's early LaMDA was probably wrong

In a 14-minute Intelligence Squared video published 15 October 2026, DeepMind chief Demis Hassabis, in discussion with Sebastian Mallaby, discussed Google's early LaMDA product.

17 OCT · Google DeepMind · 2 sources
Tooling

How spend and rate limits cap what an AI agent costs

Anthropic's documentation separates monthly spend limits from per-minute rate limits and shows where each applies to API use and to Claude Code.

17 OCT · Anthropic · 2 sources
In brief 3 more today
0 of 3 read
Drag a card to start Drag left or right · tap to read more Hover to lift a card · tap to bring it forward Tap again to put it back Tap a card to open it Tap again to close it Tap a headline to read it as a card